
tu_nlp_byte_transformer — Byte × Transformer
Source-owned OA v0.12.0 SDK tutorial. Recorded results qualify the named device and driver.
The byte-tokenizer × Transformer cell of the — same 576-character corpus, same 300-step recipe and captured training lifecycle. This entry selects the tokenizer and model shown below. See for the full walkthrough.
This cell
| Tokenizer | the 256-token packed-U8 byte vocabulary (ByteSampler) — one token per source byte |
| Model | Byte + position Embedding → Transformer(32,64) → LN → Linear(32→256) |
| Parameters | 25,760 |
| Optimizer | AdamW(lr=0.01) — the canonical recipe |
The loop is a prepare/record pair per step — GradientTape → cross_entropy → backward → AdamW —
driven by oa::ml::ItTraining, so the whole run is one captured GPU program replayed
299 times (46 nodes for this model).
Measured — Surface Laptop 5 (ADL GT2)
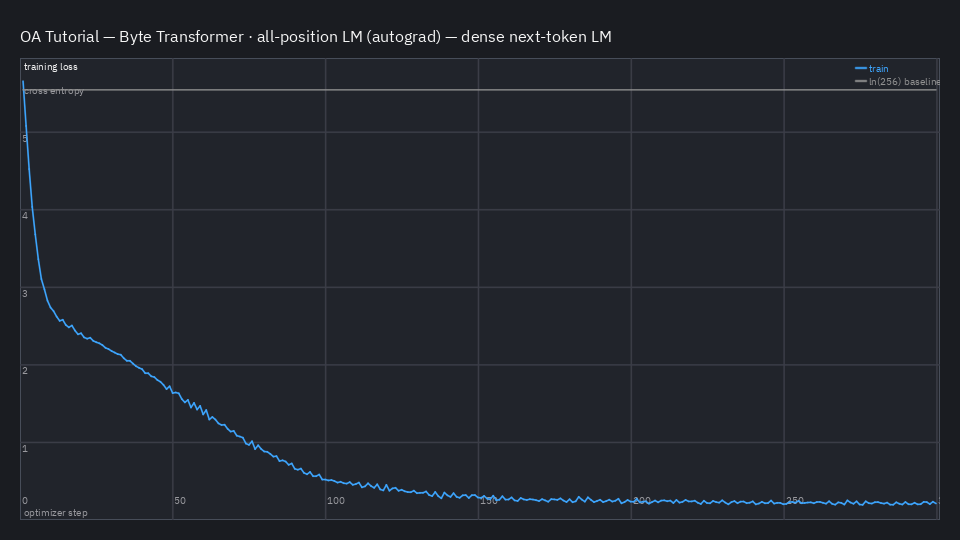
Canonical 300-step training loss, recorded by this tutorial.
| Loss init→final | Accuracy | Program nodes | Wall ms/step | Token/s |
|---|---|---|---|---|
| 5.657→0.201 | 92.9% | 46 | 7.85 | 130.5K |
Reference generation on the default recipe (asserted by the tutorial):
1prompt: "to be"2generated: "to be that is the question whether tis nobler in the mind to suffer the slings and ar"3
Run
cargo run --release -p sdk --example tu_nlp_byte_transformer
Regenerate the training-loss image from the repository root:
cargo run --release -p sdk --example tu_nlp_byte_transformer -- --plot sdk/rs/tutorials/ml/nlp/tu_nlp_byte_transformer/asset/training-curve.png
On the default recipe the tutorial self-tests: loss regime, accuracy
floor, exact reference generation, and .oam checkpoint round-trip.
Terminal output
Recorded canonical 300-step run on Intel Iris Xe (ADL GT2), Mesa 26.2.7. Startup logs, intermediate progress updates and the plot-save path are omitted. Timings vary by run; these are not new benchmark baselines.
╔══════════════════════════════════════════════════════════════════╗║ OA Tutorial — Byte Transformer · all-position LM (autograd) ║╚══════════════════════════════════════════════════════════════════╝tokenizer: raw bytes · vocab=256Task: dense next-byte prediction at every positionModel: Byte + position Embedding → Transformer(32,64) → LN → Linear(32→256)params: 25760 Optimizer: AdamW(lr=0.01)300/300 |██████████| 2.14s · 7.13 ms/step · 8.98K sample/s · 143.68K byte token/s · 143.68K byte/s · loss: 0.2005Summary:loss: initial 5.656755 · final 0.200502 · mean 0.756808Wall: 7.13 ms/step · 8.98K sample/s · 143.67K byte token/s · 143.67K byte/sGPU (byte_transformer_training_step): mean 6.310 ms/step · p50 4.861 · p95 13.006 · min 4.053 · max 16.328 · 10.14K sample/s · 162.28K byte token/s · 162.28K byte/s · wall-GPU gap 11%run: 2.14s · 300 steps · batch 64 · sequence 16 byte token/sampleEvaluation:Random-loss baseline ln(256) = 5.5452byte-token accuracy: 92.9%post-update evaluation loss: 0.190566Generation:prompt: "to be"generated: "to be that is the question whether tis nobler in the mind to suffer the slings and ar"program: 46 nodes · 1 recording · 299 cache hits · 0 uploadscheckpoint: optimizer step, accuracy, and exact generation restored